Data lineage is the end-to-end record of where data comes from, how it moves, and how it changes across reports, dashboards, and AI models that use it. It lets you trace any number back to its source, see what a change will break downstream, and show auditors the path your data took.
In short:
What it shows: the origin, movement, and transformations of data across systems, down to the individual column.
Why it matters: faster root-cause analysis, safer changes, audit readiness, and trust in the data feeding analytics and AI.
How it’s captured: automatically, by parsing SQL and query logs, extracting BI and dbt metadata, and ingesting OpenLineage events, with manual lineage filling the gaps.
What’s new: Alation Lineage now covers file sources and cross-database movement, stays current as views and dbt models change, and can be queried through APIs and agents. See what’s new in Alation Lineage.
Imagine running your business with no idea where your data came from, how it changed, or whether you can trust it. As cloud stacks grow more complex and AI systems depend on accurate inputs, the risk of decisions made on faulty data multiplies. In a 2025 survey commissioned by SoftServe and conducted by Wakefield Research, 58% of 750 business and technology leaders at companies with $1 billion or more in annual revenue said key business decisions are based on inaccurate or inconsistent data most of the time, if not always.¹ Separately, 63% of organizations either do not have, or are unsure whether they have, the right data management practices for AI, according to Gartner.²
That’s why lineage has become a business requirement, not just a technical tool. With it, teams can see how data flows, where it breaks, and how to fix it. In this guide, we define data lineage, explain how it works, and show how to implement it and overcome common challenges.
What is data lineage?
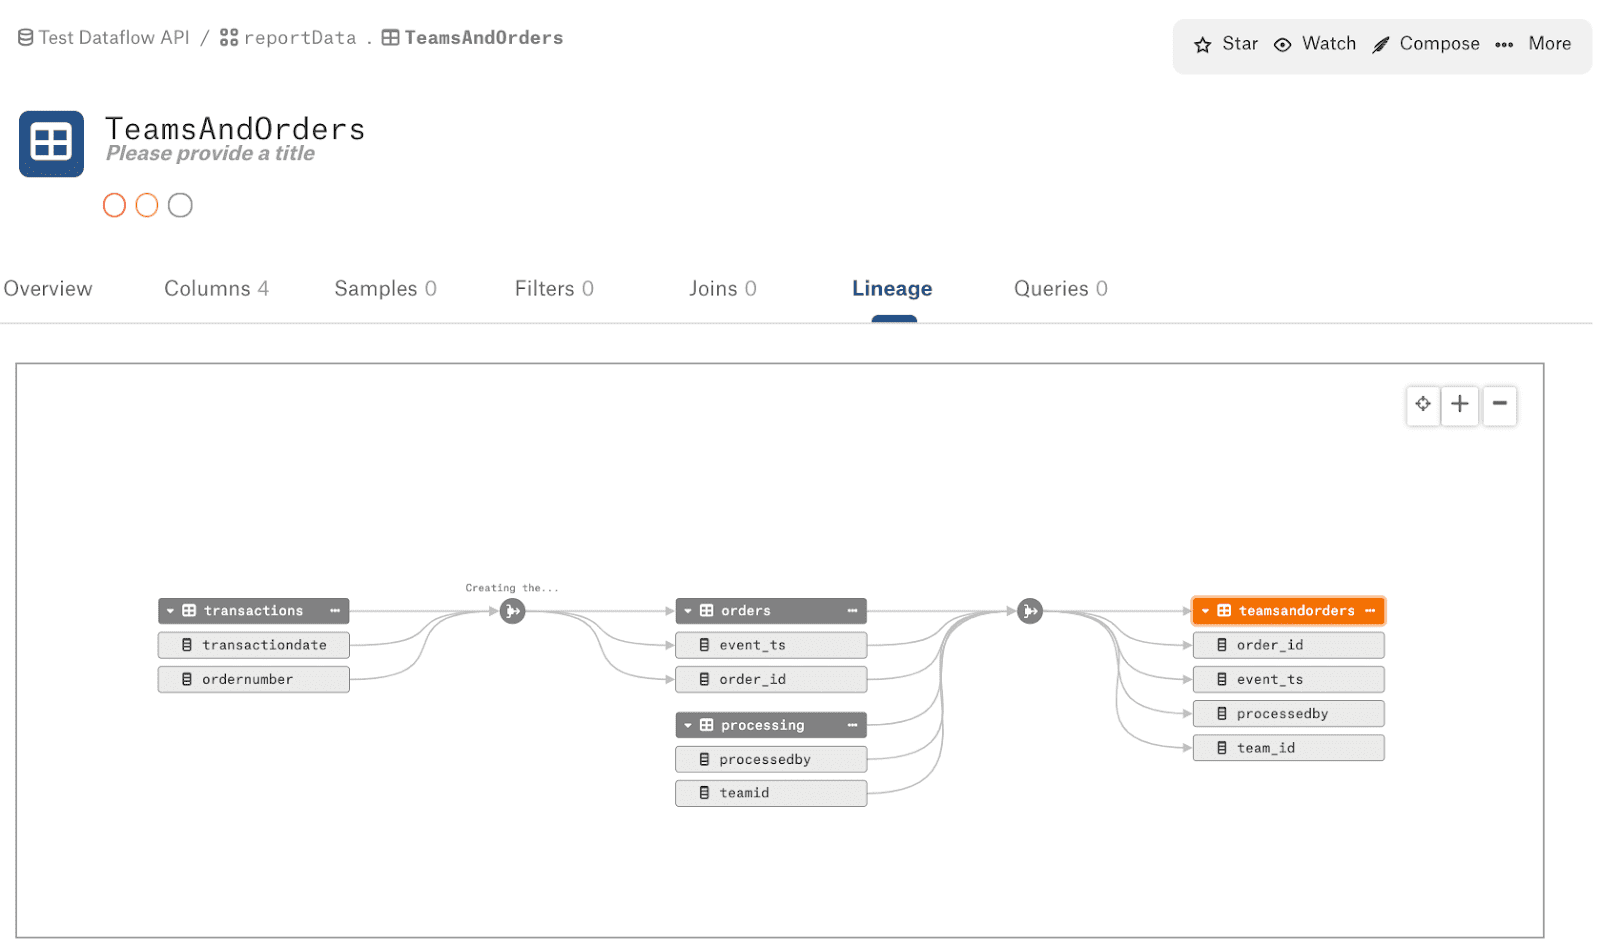
Data lineage is the story behind your data: where it originated, how it has changed, and every transformation it has gone through. It traces a dataset’s lifecycle across systems and pipelines, showing each enrichment, filter, join, calculation, and aggregation that shapes its final form.
That visibility is critical for spotting errors, validating analytics, performing root-cause analysis, and building trust in the numbers leadership sees. Lineage also supports governance, audit readiness, and data quality by connecting the dots across databases, cloud platforms, and BI tools.
Lineage can be captured and visualized at several levels:
Table-level lineage tracks how datasets are transformed across pipelines.
Column-level lineage follows how individual fields are modified, calculated, or derived.
Business lineage connects technical assets to the reports, KPIs, and business processes that depend on them.
Cross-system lineage follows data across databases, cloud platforms, file sources, and BI tools.
Together, these views combine technical, business, and operational context to support everything from compliance to innovation.
What’s the difference between data lineage, data mapping, and data provenance?
These terms are related but answer different questions:
Data lineage | Data mapping | Data provenance | |
|---|---|---|---|
Question it answers | Where did this data go, and what happened to it? | How do fields in one system correspond to fields in another? | Where did this data originate, and in what context? |
Nature | Ongoing, captured from actual data movement | A defined design step, usually done up front | The origin and history of a specific asset |
Typical use | Impact analysis, root-cause analysis, audits | Integration and migration projects | Verifying source and authenticity |
Data mapping defines relationships between fields to enable integration, such as how customer names in a CRM correspond to records in a warehouse. Lineage captures what actually happens to data as it moves, including transformations, aggregations, and dependencies. Provenance focuses on the origin of a given data asset, while lineage follows that asset across its whole journey.
The 7 benefits of data lineage
When teams can track information from source to destination, they can improve business results directly. Here’s a closer look at the benefits of data lineage:
Assess downstream impact: Lineage shows what a change will affect before you make it. For retailers, that might mean understanding how stock-level changes flow into sales forecasts, or how a new field alters dashboard calculations.
Accelerate root-cause analysis: Combined with metrics like data freshness and pipeline execution times, lineage helps engineers pinpoint when and where a data quality issue began, so they can resolve it faster.
Optimize resource allocation: Lineage maps how your company uses data, exposing duplicate reports and outdated processes.
Enforce stronger data governance: Complete visibility into data flows lets teams refine policies and protect sensitive information. In financial data, for instance, lineage helps distinguish transaction data from aggregated metrics so the right governance rules apply to each.
Automate and improve data quality: Paired with observability and quality tools, lineage improves issue detection and keeps data reliable.
Improve compliance and risk management: By mapping how data changes, lineage helps you quickly identify assets affected by regulations such as GDPR for personal data or HIPAA for healthcare information.
Prepare for audits: Accurate records and audit trails make reviews faster and less disruptive.
How data lineage works across systems
Lineage platforms discover relationships automatically instead of relying on manual documentation. Common capture methods include:
Parsing SQL and query logs to infer how tables and columns relate.
Extracting metadata from BI tools and transformation tools like dbt, which reveals how models and reports depend on their sources.
Ingesting OpenLineage events from orchestration and processing engines such as Spark and Trino.
Adding manual lineage where movement happens outside any tool the platform can parse, such as custom scripts.
These methods connect to databases, cloud warehouses, ETL pipelines, and analytics platforms to capture transformation logic. The result is a graph of upstream dependencies and downstream impacts, which teams use to find root causes during pipeline failures.
Enterprise lineage works at multiple levels. Dataset-level lineage maps table relationships and file dependencies. Column-level lineage traces field transformations, calculations, and joins, which is critical for complex workflows involving filtering, pivoting, and aggregation. Business lineage connects technical assets to KPIs and reporting metrics.
Because the graph is generated from the systems themselves, it can evolve with your stack, from raw ingestion through to BI dashboards, rather than going stale in a spreadsheet. For a deeper look at the different approaches, see our guide to automated data lineage.
How to implement data lineage
Successful implementation balances technical capability with business need. Start with clear objectives and build incrementally.
1. Define your data lineage goals
Different organizations have different priorities. Establish your goals first, so you know which aspects of lineage to implement first and how to measure success.
If your main goal is regulatory compliance, start with column-level lineage for sensitive fields (PII, financial records) and measure success by audit readiness. If your goal is operational efficiency, start with the datasets used most often and any redundant processes, and track signals like lower data preparation time and fewer duplicate workflows.
Focus first on the business processes that rely most on accurate data and the systems that would cause the biggest problems if they failed. That demonstrates value quickly and builds momentum for a wider rollout.
2. Establish governance roles
Lineage depends on clear ownership. Data stewards oversee subsets of organizational data to ensure quality, integrity, and security. They bridge technical and business teams, maintain lineage accuracy, and document business rules.
Create a process for handling lineage gaps and inconsistencies. Stewards enrich automated lineage with business context, validate relationships, and make sure governance policies match how the business actually works. Regular reviews show where you need more documentation or better system integration.
3. Choose the right tools
Lineage platforms differ. Some focus on automated scanning of existing systems, others on manual documentation and business context. Evaluate tools against four questions:
Coverage: Does it reach your warehouses, BI tools, files, and the places data moves outside parsed tools?
Granularity: Does it provide column-level technical lineage as well as business lineage?
Freshness: Does the graph update when views, models, and sources change, or does it accumulate stale links?
Access: Can people and agents use lineage in the catalog, through APIs, and in analytics, not just in a diagram?
Alation Lineage is built around these criteria. See how data lineage works in Alation below, or read the October 2026 product update for details. For a broader comparison of options, see our guide to data lineage tools.
4. Map data flows and establish lineage paths
Start with the flows that directly affect business decisions or regulatory reporting. Document them manually if necessary, but prioritize areas where automated discovery delivers immediate value.
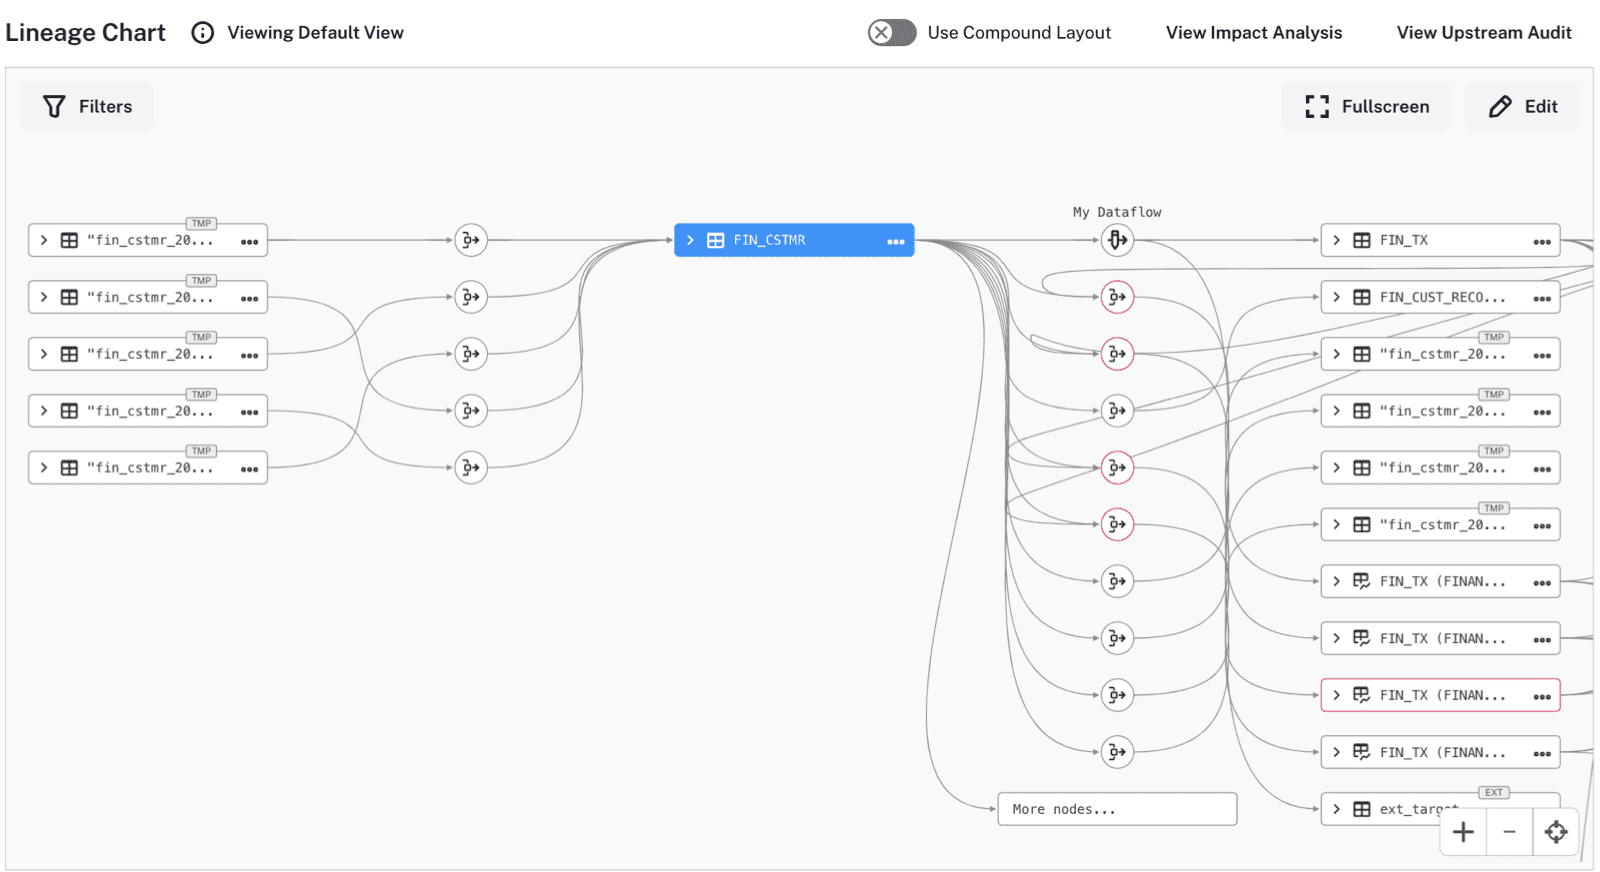
Focus on entire end-to-end journeys rather than individual system connections. Business users want to understand how reports connect to source systems, while technical teams need detailed transformation logic. Complete overviews show value to both audiences.
5. Integrate lineage with existing systems
Lineage is most valuable when it sits inside daily workflows. Connect it to your data catalog so analysts can see sources while building reports. Integrate it with incident management so data quality issues automatically surface relevant lineage.
Consider how lineage fits into development and deployment. When engineers update transformation logic, the lineage should adjust automatically. When analysts build a new report, they should be able to check its sources and limitations.
6. Maintain and review regularly
Accurate lineage takes ongoing effort. Schedule routine reviews to spot gaps, double-check automatic discoveries, and update business context as systems change. Monitor lineage completeness across your ecosystem, since gaps highlight systems that need better integration. Regular audits confirm that metadata reflects real business processes, not just technical connections.
Addressing common challenges related to data lineage
Lineage programs run into predictable obstacles. Here are three to plan for.
Tracking lineage across complex, hybrid data ecosystems
Coverage suffers when data spans cloud warehouses, on-prem databases, files, and SaaS applications. Start with the most impactful flows rather than trying to cover everything at once. Business lineage links technical flows to business processes, so teams can see which systems drive value. Following customer transaction data from payment systems through fraud detection to revenue dashboards, for example, shows how each technical component contributes to business outcomes.
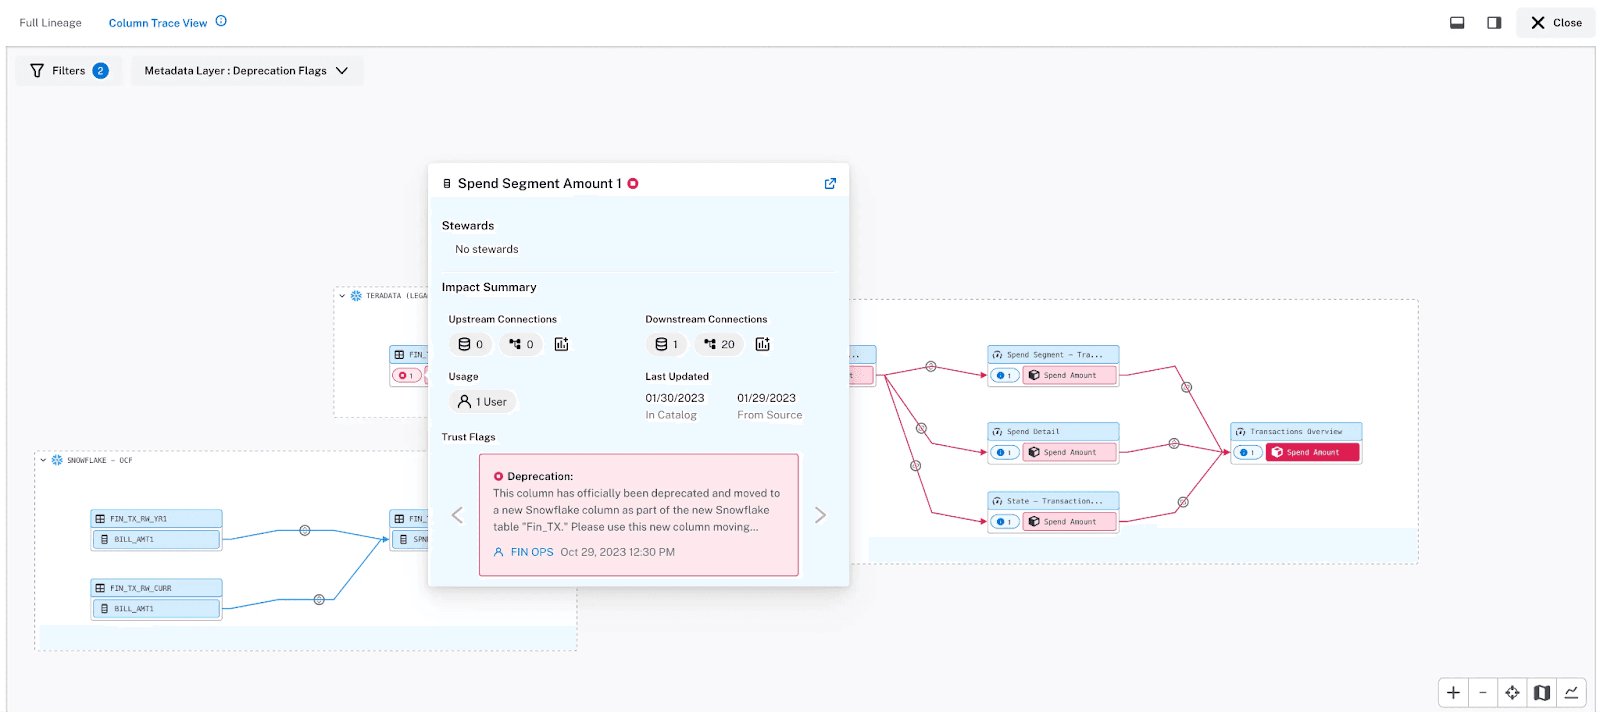
Also watch for gaps that automation misses. Spreadsheets feeding BI workbooks, custom scripts moving data between databases, and events whose identity doesn’t match the cataloged source can all leave the graph blank. Look for tooling that handles these sources explicitly.
Diagnosing data pipeline failures with precision
When data pipelines fail or produce unexpected results, an issue in one system can ripple through many downstream processes. Lineage acts as a roadmap: instead of checking every system manually, teams trace the flow backward from the point of failure to the root cause. That shortens mean time to resolution and prevents teams from fixing symptoms instead of underlying problems.
Lineage also shows which downstream reports and dashboards are affected, so you can prioritize fixes by business impact and identify alternative sources to use temporarily.
Handling complex transformations
Machine learning pipelines, intricate business logic, and real-time processing are hard to capture automatically, and gaps reduce trust in the data. A hybrid approach works best: automated discovery plus collaborative documentation, where engineers and analysts add the context automation often misses. The result is a more accurate record, even in complex environments.
A related risk is staleness. Views get rewritten, dbt models get edited, and sources get retired, and a stale link is worse than a missing one because it looks trustworthy. Choose tools that replace old connections as logic changes, and that clearly distinguish deleted, temporary, and uncataloged objects.
How data lineage works in Alation
As of October 2026. For feature-by-feature detail, see What’s New in Alation Lineage.
Alation Lineage builds the graph automatically from query logs, BI tools, dbt models, and OpenLineage events, and lets teams add manual lineage where automation can’t see. Recent updates focus on three things:
Fuller coverage. File-based sources, such as a CSV or Excel file behind a Tableau workbook, now appear as nodes in the graph. Alation can build table- and column-level lineage between two relational databases by matching object names once an admin declares the upstream source. OpenLineage events from tools like Spark and Trino now resolve to cataloged sources (including AWS Glue, Hive Metastore, Trino, Athena, and Redshift), rather than silently producing no lineage.
A graph that stays current. Version-aware lineage replaces the old connection with the new one when a database view or dbt model changes, at both table and column level. Admins can opt in to separate badges for temporary, deleted, and uncataloged objects, and can scope query-based lineage to a recent time window. Impact Analysis and Upstream Audit trace through temporary objects to the permanent tables behind them.
Lineage where the work happens. Lineage in Alation Analytics is generally available, so you can run impact analysis and custom reporting over the whole graph. Enhanced lineage APIs support filtering by direction and bulk cleanup. Lineage Co-Pilot (open beta) can diagnose why a graph is empty and answer questions in context. Agent Studio includes a Lineage Agent and a Lineage Builder Agent for tracing and managing lineage with approval controls.
For regulated industries, Critical Lineage in Critical Data Manager builds on the core lineage graph. It traces a specific metric in a filing back to its source with an accountable chain of ownership.
Availability: These updates are available to Alation Cloud Service customers. Some are on by default, such as lineage in Alation Analytics and file-to-BI lineage, and others are opt-in. Most apply going forward, so existing historical links may need cleanup with your Alation account team.
How data lineage connects to governance automation and AI compliance
Understanding where your data came from is only half the story. The harder question, and the one regulators, auditors, and AI systems are all asking, is whether the data along that lineage path meets the standard it’s supposed to meet.
Curation Automation for outcome-based governance. Lineage tells you how data moves, but tracing a calculation to its source has limited value if the assets along the path lack ownership, classifications, or documentation. Curation Automation lets administrators state metadata standards once in plain language, such as what a good description contains, what an asset needs before certification, and which fields a domain owner must fill. Agents apply those standards across the catalog. Suggestions must clear a confidence threshold and can be previewed; every edit is traceable, and rules re-run as data changes.5
In financial services, regulators expect firms to aggregate and report risk data reliably. In the Basel Committee’s 2023 review, only two of the 31 global systemically important banks assessed were fully compliant with its risk data principles.⁴
AI governance and the data dependency problem. Tracing data is only half of the governance problem. In a Gartner survey of 360 IT leaders in the second quarter of 2025, only 23% said they were very confident in their organization’s ability to manage security and governance when deploying GenAI tools.³
Alation AI Governance provides a single inventory of AI models and agents, ingested from the platforms where they run. Each asset links to the use case it serves and the data it depends on. Model cards are drafted from asset metadata with gaps flagged, and approvals route through risk-tiered workflows mapped to frameworks including the EU AI Act, NIST AI RMF, ISO 42001, and GDPR.and ISO 42001. It extends the lineage foundation: each AI asset’s data dependencies are surfaced with live data quality scores, and approval workflows evaluate whether the underlying data is certified. When an auditor asks whether a credit model’s training data was governed, the evidence is already in the system and drillable from the executive dashboard to the individual column.5
Lineage is no longer only a tool for debugging pipelines or validating reports. It is becoming the evidentiary layer that proves both data governance and AI governance are working.
Frequently asked questions about data lineage
What is data lineage in simple terms?
Data lineage is a record of where data came from, how it moved, and what changed it along the way. It works like a map from a source system to a report or AI model, so you can trace any number back to its origin and see what depends on it.
What is the difference between data lineage and data provenance?
Provenance records the origin and original context of a data asset. Lineage follows the full journey, including every system and transformation between source and destination. Provenance tells you where data started; lineage shows where it went and what happened to it.
What is column-level lineage?
Column-level lineage traces how individual fields are created, transformed, and combined, including calculations, joins, and aggregations. It is more precise than table-level lineage, which only shows which tables feed which. Teams use it to trace sensitive fields such as PII, validate how a metric is calculated, and assess the impact of a change.
How is data lineage captured?
Modern platforms capture lineage automatically by parsing SQL and query logs, extracting metadata from BI tools and transformation tools like dbt, and ingesting OpenLineage events from engines such as Spark and Trino. Manual lineage fills the gaps where data moves through custom scripts or tools that can’t be parsed.
Why does data lineage matter for AI?
AI models and agents are only as trustworthy as their inputs. Lineage shows which sources feed a model or agent, whether those sources are governed and certified, and what an upstream change will affect. It also provides the audit evidence that AI governance frameworks increasingly call for.
Can Alation build lineage between databases without a parsed ETL tool?
Yes. Alation can build table- and column-level lineage between two relational databases by matching object names, once an admin declares the upstream source in the target’s lineage settings. Query-based lineage requires the same database type on both sides, and script-based lineage requires matching table names.
The future of data lineage and how to be ready
Data lineage is evolving. Trends include more automation, smarter systems, and tighter integration with business processes. AI will likely take over repetitive curation work, flag quality issues, suggest improvements to data flows, and recommend the best sources for a given need. AI governance frameworks will also depend on lineage to confirm that models use the right, high-quality data, and agents are beginning to consume lineage directly through APIs and tools.
To prepare, build strong lineage foundations now. Use platforms that automate discovery, keep the graph current, and encourage collaboration. Link technical lineage to business context, and build a culture where lineage informs everyday decisions. Done well, lineage lets you make data-driven decisions with confidence, at scale, across the organization.
Ready to see it in action? Explore Alation Lineage or talk to our team.
Sources & notes
Every external claim on this page is independently verifiable. The public sources are listed here.
58% of 750 business and technology leaders at $1B+ companies said key decisions are based on inaccurate or inconsistent data most of the time, if not always. Survey commissioned by SoftServe, conducted by Wakefield Research. SoftServe press release, 6 February 2025.
https://www.softserveinc.com/en-us/news/bad-data-makes-bad-decisions
63% of organizations either do not have or are unsure they have the right data management practices for AI; Gartner advises that organizations with basic or manual metadata management will struggle to make data AI-ready. Gartner, “Lack of AI-Ready Data Puts AI Projects at Risk,” 26 February 2025.
Only 23% of 360 IT leaders surveyed in Q2 2025 were very confident in managing security and governance when deploying GenAI tools; organizations with successful AI initiatives invest up to four times more in data and analytics foundations. Gartner press release, 16 April 2026.
Of 31 global systemically important banks assessed, only two were fully compliant with all BCBS 239 Principles. Basel Committee on Banking Supervision, “Progress in adopting the Principles for effective risk data aggregation and risk reporting,” 28 November 2023. https://www.bis.org/bcbs/publ/d559.pdf
Alation product descriptions (not independent sources): What’s New in Alation Lineage, 8 Oct 2026; Curation Automation; AI Governance. Pages checked 21 October 2026.
ANALYST ATTRIBUTIONS & DISCLAIMERS
Gartner, “Lack of AI-Ready Data Puts AI Projects at Risk” (Q&A with Roxane Edjlali), 26 February 2025.
Gartner, “Gartner Says Organizations with Successful AI Initiatives Invest Up to Four Times More in Data and Analytics Foundations,” press release, 16 April 2026.
Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose. GARTNER and Magic Quadrant are registered trademarks and service marks of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved.
- Data Catalog
- Modern Data Stack
- Enterprise Data Catalog
- Data Governance
- Active Data Governance
- AI
- Digital Transformation
- Engineering
Keep reading
More from the data desk